FrontierSimon Willison
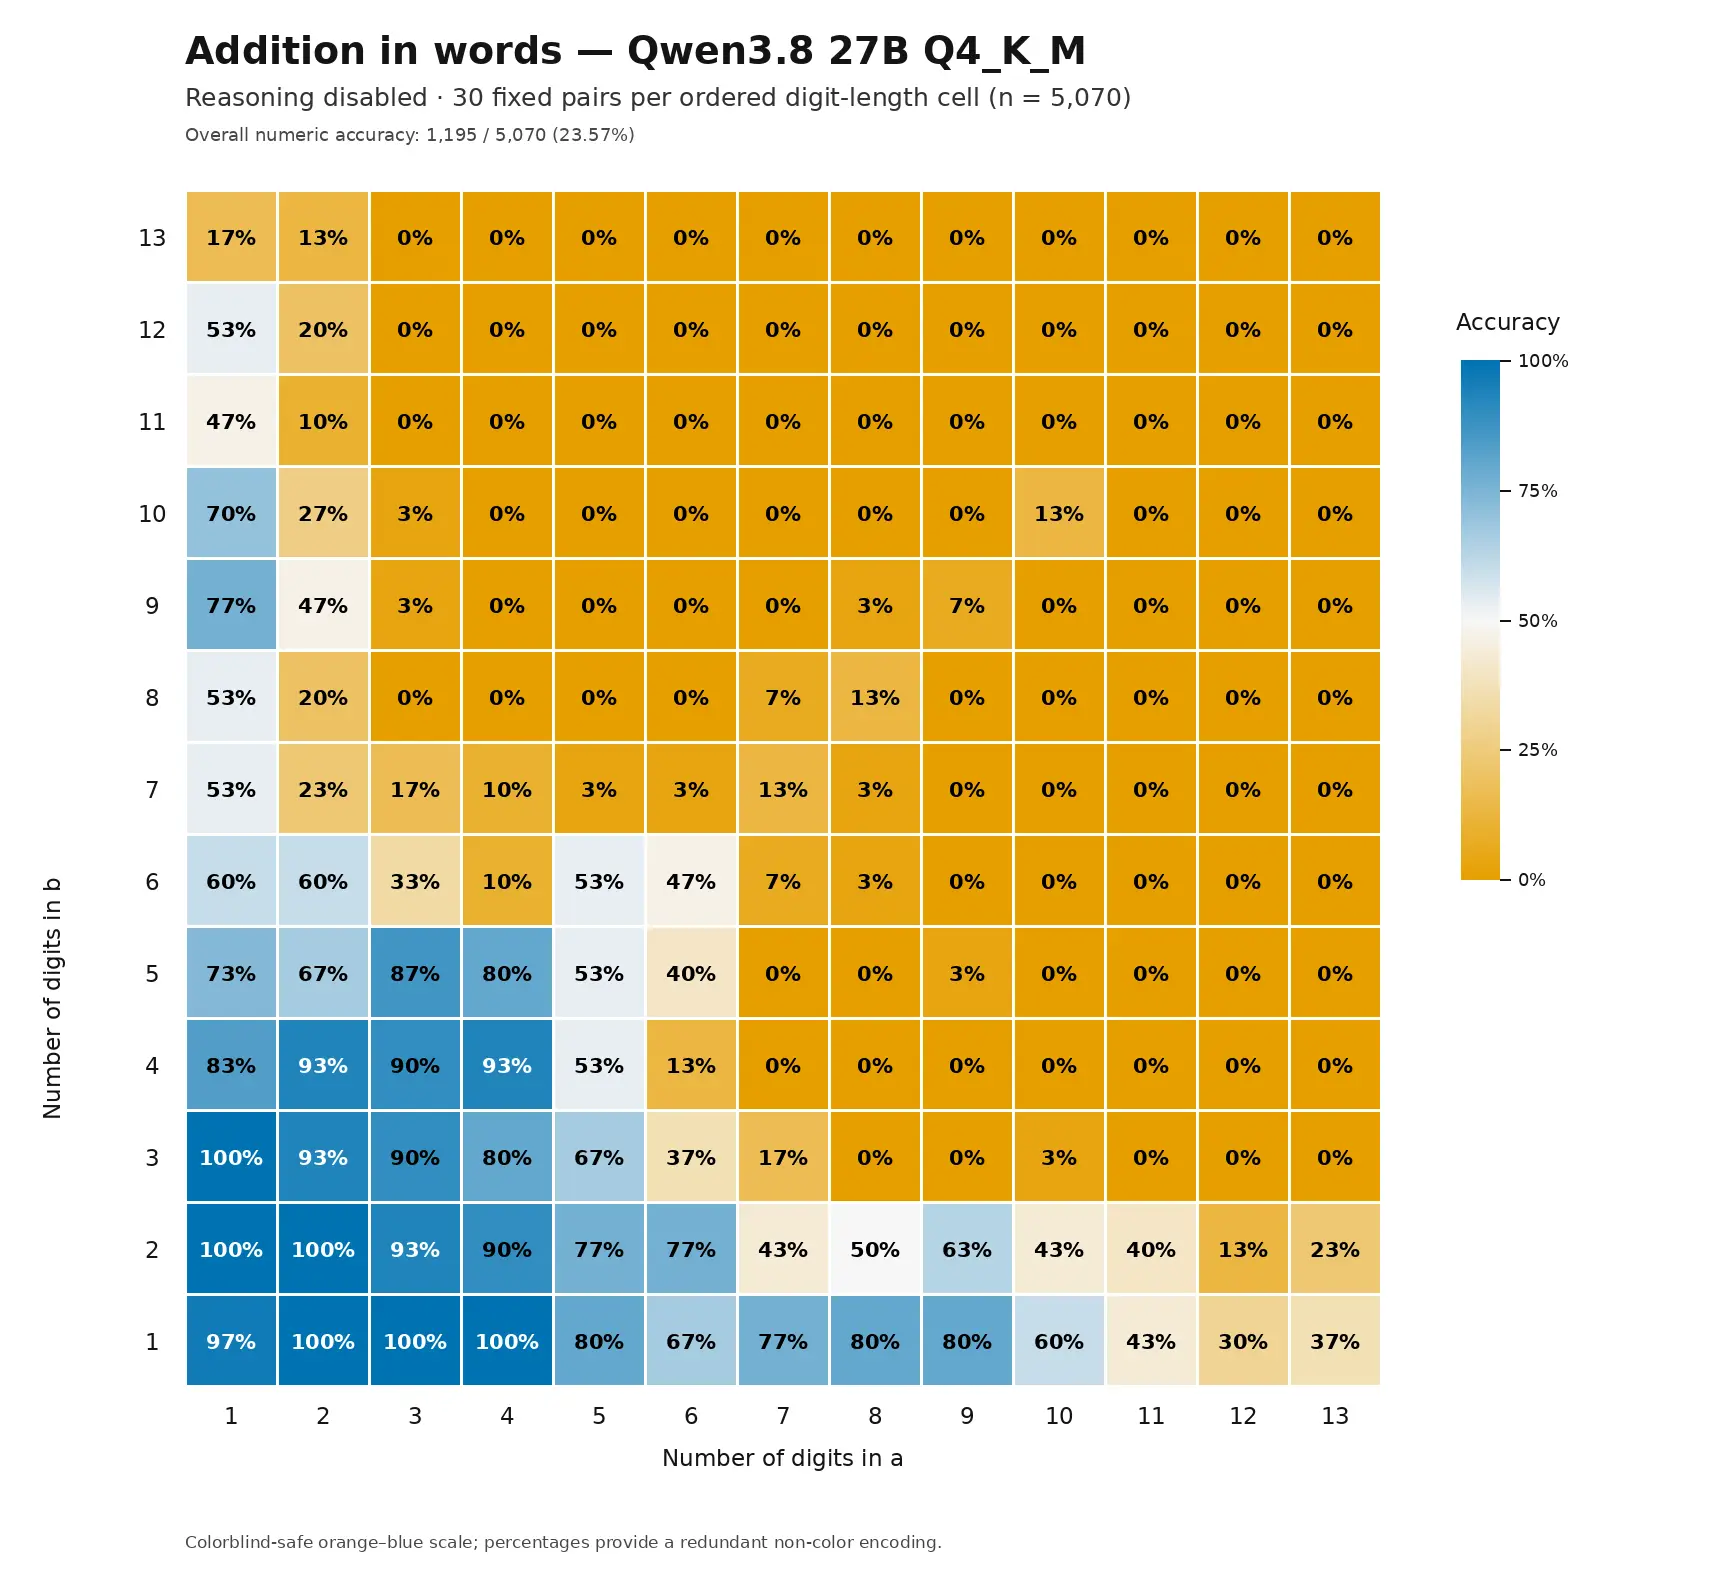
KeyRank 72Qwen3.8 27B addition in words
Qwen3.8 27B adds native multi-token generation ('addition in words'), reducing inference latency for open-weight deployments. This is a meaningful capability gap-closer against proprietary reasoning models, with direct implications for enterprise inference budgets and on-prem deployment economics.
2026-10-04
Read full story